Evidence Chain
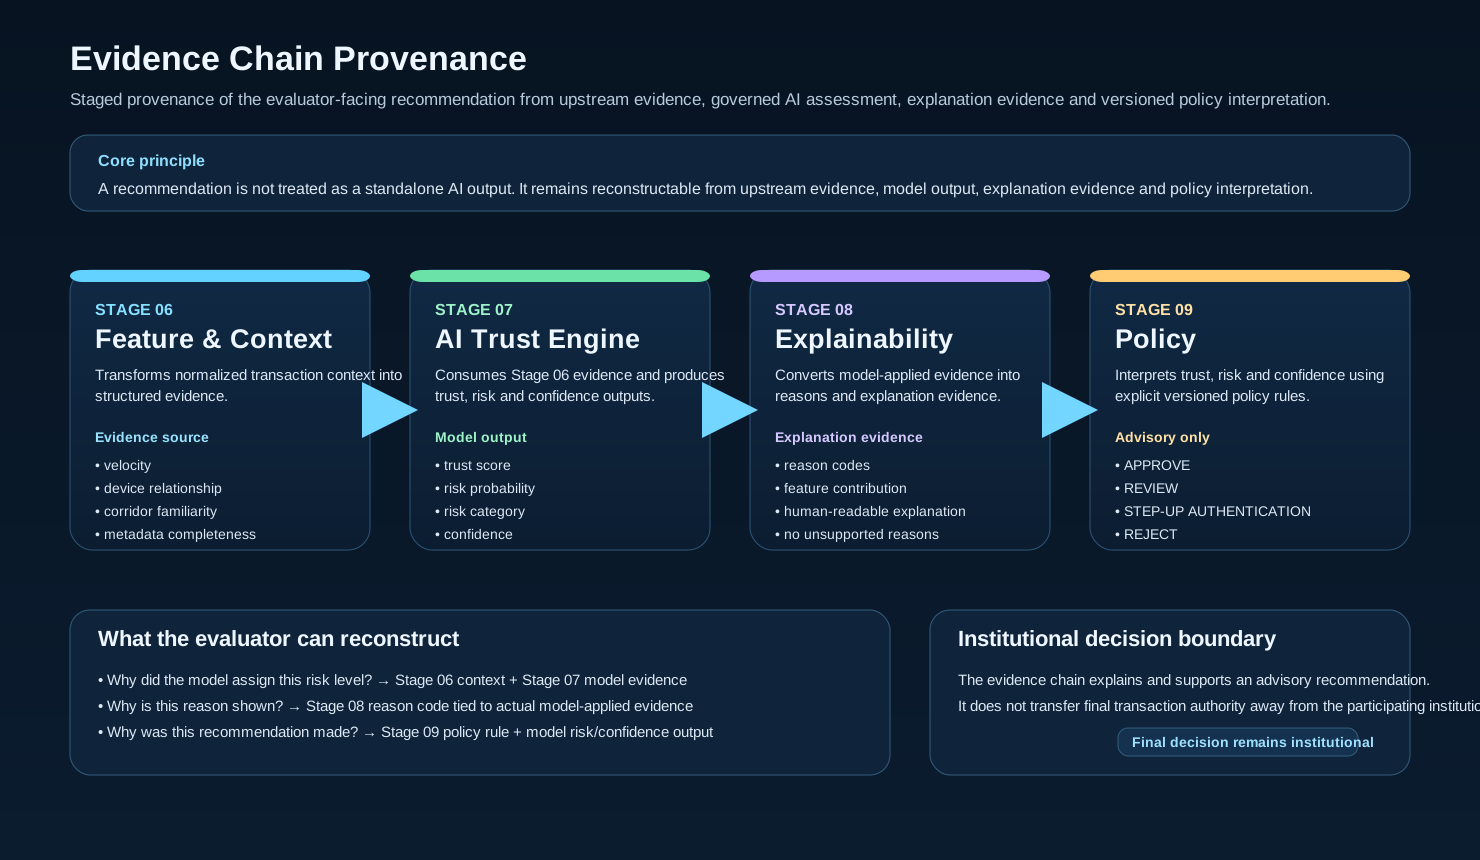
Every displayed TRUST outcome is assembled from a traceable sequence of implementation stages. This page shows where each result originates and how it contributes to the final recommendation.
Core principle
A recommendation is not treated as a standalone AI output. It must remain reconstructable from upstream evidence, model output, explanation evidence and policy interpretation.
Traceable Assessment Chain
Stage 06 — Feature & Context
Transforms normalized transaction context into structured evidence such as velocity, device relationship, corridor familiarity, relationship maturity, authentication assurance and metadata completeness.
Evidence sourceStage 07 — AI Trust Assessment
Consumes Stage 06 evidence and produces the trust score, risk probability, risk category and confidence score.
Model outputStage 08 — Explainability
Converts only model-applied evidence into reason codes, feature contributions and a human-readable explanation. Unsupported reasons must not be invented after scoring.
Explanation evidenceStage 09 — Policy
Interprets the trust, risk and confidence assessment through explicit versioned policy rules to generate an advisory recommendation.
Advisory onlyWhat the Evaluator Can Verify
| Question | Evidence expected |
|---|---|
| Why did the model assign this risk level? | Stage 06 context plus Stage 07 applied model features. |
| Why is this reason shown? | Stage 08 reason code corresponding to an actual model-applied feature. |
| Why was this recommendation made? | Stage 09 policy rule plus model risk/confidence output. |
| Can the result be reconstructed? | Yes. Transaction ID, model version, policy version, reasons and audit evidence remain linked. |
Evidence Chain Provenance
This visual presents the staged provenance of the evaluator-facing evidence chain.